The Pitfall of Serving MoE LLMs: Why GPU Memory Estimates Go Wrong When You Only Look at Parameter Count
Research has consistently shown that LLMs perform better as parameter counts scale up, driving companies like Meta, Google, and OpenAI to competitively release ever-larger models. However, as models grow, so does the compute cost required to train and serve them. Mixture of Experts (MoE) emerged precisely to address this tension — enabling larger LLMs to be trained and served at lower cost.
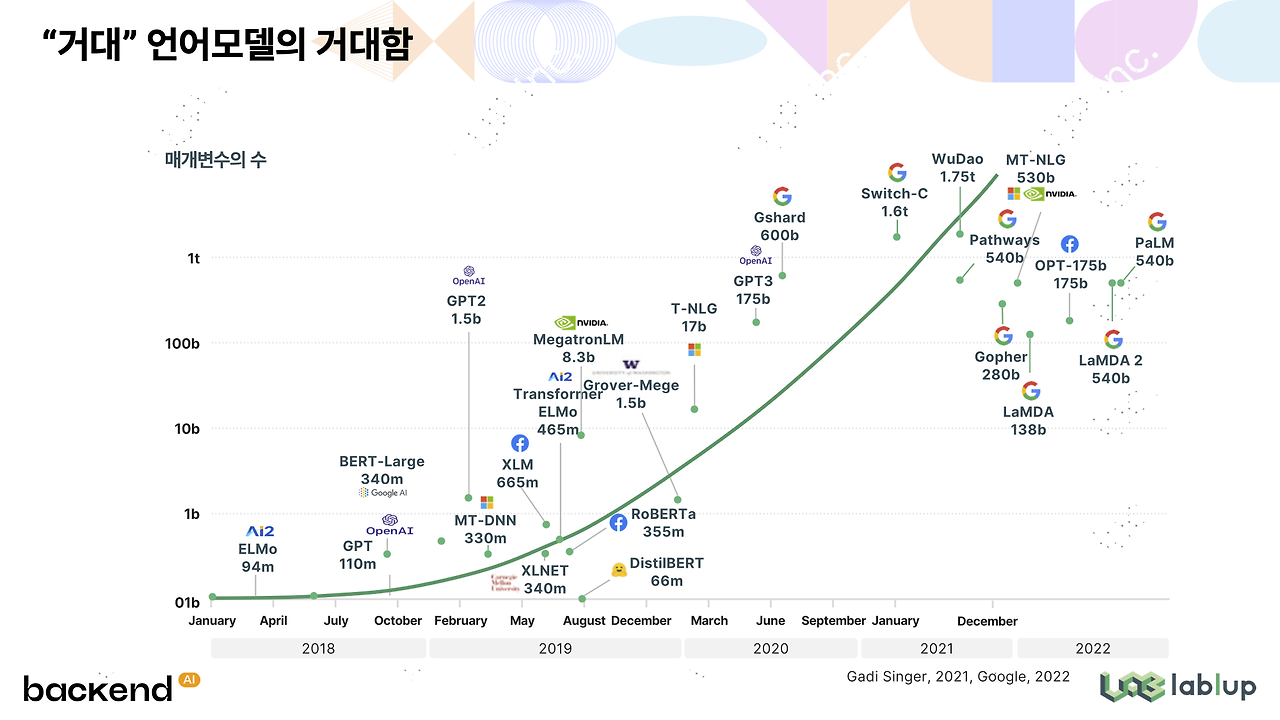
One of the most prominent MoE models is Mistral AI's Mixtral-8x7B. OpenAI's GPT is widely suspected to use a MoE architecture as well, though the exact design has never been disclosed. MoE models achieve efficient inference by activating only a subset of total parameters per forward pass.
MoE: Basic Architecture and How It Works
The core concepts behind MoE are:
- Expert Networks (Experts): A MoE model consists of multiple independent neural networks, each called an "expert." A typical model may include anywhere from hundreds to thousands of experts.
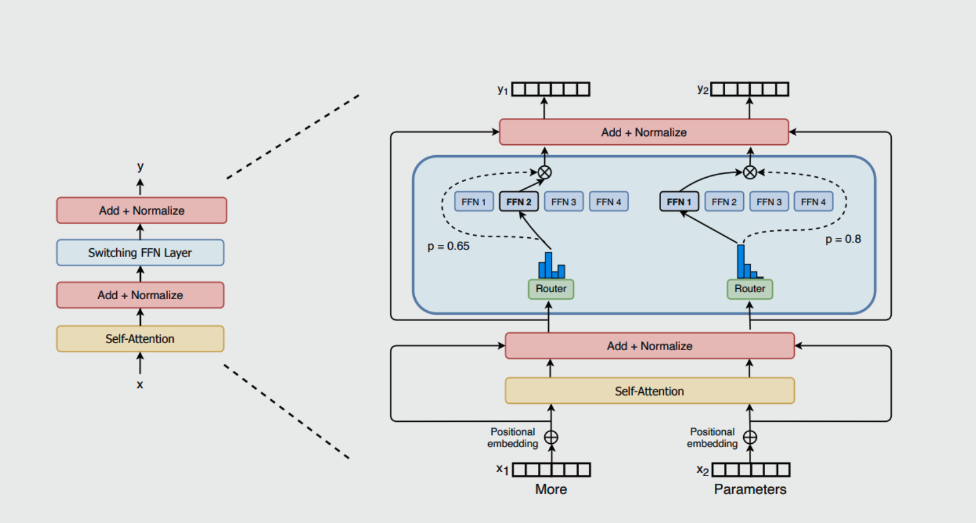
- Gate Network (Router): A network that decides which experts are activated for a given input. The router takes the input, computes a weighted combination of selected experts' outputs, and produces the final output. Typically only a few experts are activated per input token; the rest remain inactive.
MoE in the Transformer Architecture
A standard Transformer block in an LLM follows the pattern: Self-Attention → Add & Norm → FFN → Add & Norm. MoE diverges at the FFN stage: instead of a single FFN, it maintains multiple FFNs. After a token passes through Self-Attention → Add & Norm, the router directs it to a specific FFN. The next token may be routed to a different FFN entirely. In this way, the router selects a specific subset of FFNs for each token — either one or up to N experts, depending on configuration. When top-k routing is used, the token passes independently through the k selected FFNs, and the outputs are combined via a weighted sum or another aggregation method to produce the final output. The per-expert weights are typically derived from the router's computed probabilities.
Routing Variants
Common MoE routing approaches include:
- Standard MoE: Combines outputs from all experts, maximizing knowledge utilization at the cost of higher compute.
- Switch Transformer: Routes each input to exactly one expert — highly efficient, but risks information loss.
- GShard: Developed by Google; applies MoE at large scale with strong scalability across diverse tasks.
- BASE Layers: Maintains balanced load across experts during training, ensuring all experts are utilized evenly.
- HashMoE: Uses a hash function to assign experts; computationally efficient but less flexible.
- Soft MoE: Smoothly blends outputs from all experts — a middle ground between Standard MoE and Switch Transformer.
- ST-MoE (Sparse Top-k MoE): Selectively activates the top-k experts out of a large pool per input, balancing efficiency and performance for large-scale language models.
Other approaches include Expert Choice Routing and Mixture of Experts with Expert Choice (MoEC).
Token Choice vs. Expert Choice
MoE routing falls into two broad paradigms.
Token Choice: The standard approach, where each token independently selects its top-K experts. It composes naturally with autoregressive generation, but is prone to load imbalance — popular experts attract a disproportionate share of tokens. Common mitigations include capacity factor over-provisioning (2–8×) and auxiliary load-balancing losses.
Expert Choice: A reverse formulation proposed by Google in 2022, where each expert selects the top-K tokens from the batch. This guarantees perfect load balancing by construction and allows a variable number of experts per token. The downside is that expert selection requires access to the full sequence, which violates causality and makes it incompatible with standard autoregressive language models.
Key MoE Models: 2024–2025 Comparison
| Model | Total Parameters | Active Parameters | Experts per Layer | Active Experts | Load Balancing Strategy |
|---|---|---|---|---|---|
| Mixtral 8x7B | 46.7B | 12.9B | 8 | 2 | Auxiliary loss |
| DeepSeek-V3 | 671B | 37B | 256 routed + 1 shared | 8 | Bias-based (loss-free) |
| Qwen3-235B-A22B | 235B | 22B | 128 | 8 | Global-batch aux loss |
| Gemini 1.5 Pro | Undisclosed | Undisclosed | Undisclosed | Undisclosed | Undisclosed |
DeepSeek-V3 introduced a loss-free balancing approach that adds a per-expert dynamic bias term to the routing score in place of an auxiliary loss. The bias is increased for underutilized experts and decreased for overloaded ones, but crucially it is excluded from the final gating weights, so it does not affect output quality. Qwen3-MoE forgoes shared experts entirely and relies solely on a global-batch load balancing loss to encourage expert specialization.
Code Example: Mixtral-8x7B
Here is how to use Mixtral-8x7B, one of the most widely deployed MoE models:
from mistral_common.tokens.tokenizers.mistral import MistralTokenizer
from mistral_common.protocol.instruct.messages import UserMessage
from mistral_common.protocol.instruct.request import ChatCompletionRequest

# Tokenization

mistral_models_path = "MISTRAL_MODELS_PATH"

tokenizer = MistralTokenizer.v1()

completion_request = ChatCompletionRequest(messages=[UserMessage(content="Explain Machine Learning to me in a nutshell.")])

tokens = tokenizer.encode_chat_completion(completion_request).tokens

# Inference by mistral_inference

from mistral_inference.transformer import Transformer
from mistral_inference.generate import generate

model = Transformer.from_folder(mistral_models_path)
out_tokens, _ = generate([tokens], model, max_tokens=64, temperature=0.0, eos_id=tokenizer.instruct_tokenizer.tokenizer.eos_id)

result = tokenizer.decode(out_tokens[0])

print(result)

# Inference with huggingface transformers

from transformers import AutoModelForCausalLM

model = AutoModelForCausalLM.from_pretrained("mistralai/Mixtral-8x7B-Instruct-v0.1")
model.to("cuda")

generated_ids = model.generate(tokens, max_new_tokens=1000, do_sample=True)

# decode with mistral tokenizer
result = tokenizer.decode(generated_ids[0].tolist())
print(result)
Mixture of Tokens (MoT)
While MoE asks "which expert should handle this token?", Mixture of Tokens (MoT) approaches the problem from the opposite direction. Presented at NeurIPS 2024, MoT does not route tokens to experts. Instead, it first mixes tokens from multiple examples in a batch, then feeds the mixed representations into the expert FFNs.
The three key ideas are:
- At each layer, tokens from different examples in the batch are combined via learned weights into a mixed representation.
- This mixed representation is what passes through the expert FFN.
- The mixing weights are learned; the paper's ablations show this outperforms a fixed uniform weighting scheme (1/n).
The main differences from MoE are:
- MoT is continuous — there are no discrete routing decisions, so the gradient discontinuities inherent in sparse routing are avoided.
- When the number of experts equals the number of tokens, total compute matches top-1 Token Choice MoE.
- Comparative experiments in the paper show improvements over both Token Choice and Expert Choice sparse MoE in terms of training stability and expert utilization.
Because MoT mixes tokens from different examples within a batch, it operates as intended in batched inference settings rather than single-request inference.
MoE Fine-Tuning: Key Considerations
Expert Collapse
Fine-tuning a pretrained MoE model is prone to routing collapse, where the router concentrates tokens on a small subset of experts. The remaining experts receive little gradient signal and effectively stop being trained, reducing the model's overall capacity.
Load Balancing Auxiliary Loss
The standard mitigation for load imbalance is to add an auxiliary loss — typically penalizing the variance in the number of tokens received by each expert — on top of the main training loss. However, if the auxiliary loss coefficient is too large, the resulting gradient interference can conflict with the task learning signal and degrade performance. For fine-tuning, a coefficient in the range of 0.001–0.01 relative to the main loss is typical.
Loss-Free Balancing
The loss-free approach proposed by DeepSeek in 2024 achieves expert balancing without an auxiliary loss by adding a per-expert dynamic bias to the routing scores. The bias is reduced for overloaded experts and increased for underutilized ones, but is excluded from the final gating weights. This is worth considering when you want to maintain expert balance during fine-tuning without the gradient interference that auxiliary losses introduce.
Serving MoE in Practice: vLLM
The choice of parallelism strategy when serving MoE models with vLLM significantly affects memory efficiency and throughput.
Tensor Parallelism vs. Expert Parallelism
- Tensor Parallelism (TP): Configured via
--tensor-parallel-size. Shards the weight tensors of all layers — including attention — across all GPUs. - Expert Parallelism (EP): Enabled with the
--enable-expert-parallelflag. For MoE layers specifically, experts are distributed across GPUs rather than tensor-sharded. The degree of parallelism matches the configuredtensor_parallel_size.
# Mixtral 8x7B — 4-GPU Expert Parallelism example
vllm serve mistralai/Mixtral-8x7B-Instruct-v0.1 \
  --tensor-parallel-size 4 \
  --enable-expert-parallel
MLA-Based Models (DeepSeek Family)
Applying standard TP to models that use Multi-head Latent Attention (MLA), such as DeepSeek-V3, causes the KV cache to be replicated across all GPUs, wasting significant memory. As noted in the vLLM documentation, the recommended approach for these models is a hybrid strategy: Data Parallelism for attention layers and Expert Parallelism for expert layers.
# DeepSeek-V3 — 8-GPU DP+EP hybrid example
vllm serve deepseek-ai/DeepSeek-V3 \
  --tensor-parallel-size 1 \
  --data-parallel-size 8 \
  --enable-expert-parallel