Transformer does not read a sentence one token at a time in sequential order. RNNs naturally acquire order information by flowing from front to back, but Transformer's self-attention computes relationships among multiple tokens simultaneously. This makes the architecture well-suited for parallel computation, but without explicitly providing token-order information, the model has no structural way to distinguish "The cat ate the fish" from "The fish ate the cat."
Sinusoidal positional encoding solves this problem by adding position information to the Transformer input. It is the baseline positional encoding used in Attention Is All You Need, and it works by converting each token's position into a vector of sine and cosine values at multiple frequencies, then adding that vector to the token embedding.
The most important point when understanding this mechanism is not that "a position index is stamped onto the token," but rather that "a position is represented as a combination of signals at multiple wavelengths." With that framing, the formula becomes much less foreign.
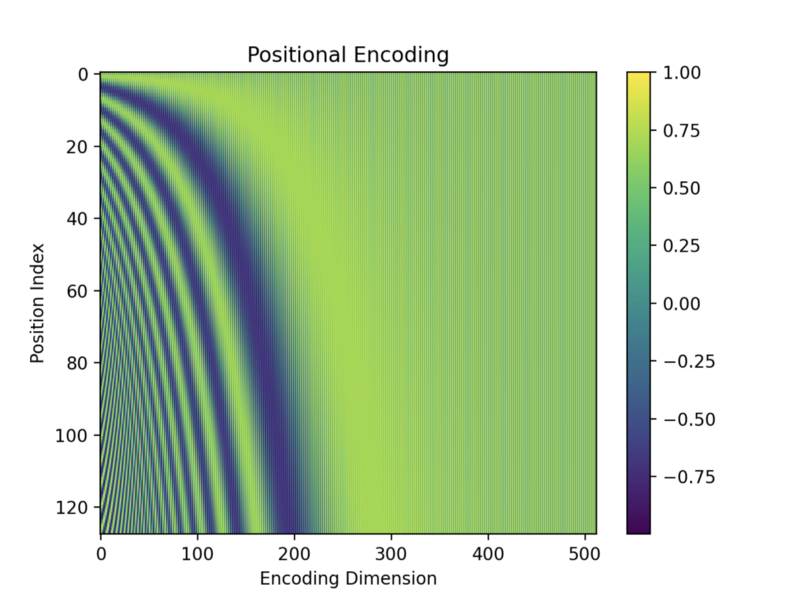
Per-position patterns of sinusoidal positional encoding. Source: Naoki Shibuya
1. Why Transformers Need Position Information
A sentence is not a bag of words — it is an ordered structure. The same words in a different order can carry a completely different meaning.
Consider these two sentences, which share nearly the same words but mean opposite things:
- The cat ate the fish.
- The fish ate the cat.
Humans parse meaning using both word choice and word order. A model must do the same: it needs to know not only what each token is, but where in the sentence it appears.
RNN-based models compute sequentially, so positional order is naturally baked into the computation flow. Transformer attention, by contrast, compares all token pairs simultaneously. That approach is fast and powerful, but without an explicit mechanism, the information about which token comes at which position is lost entirely.
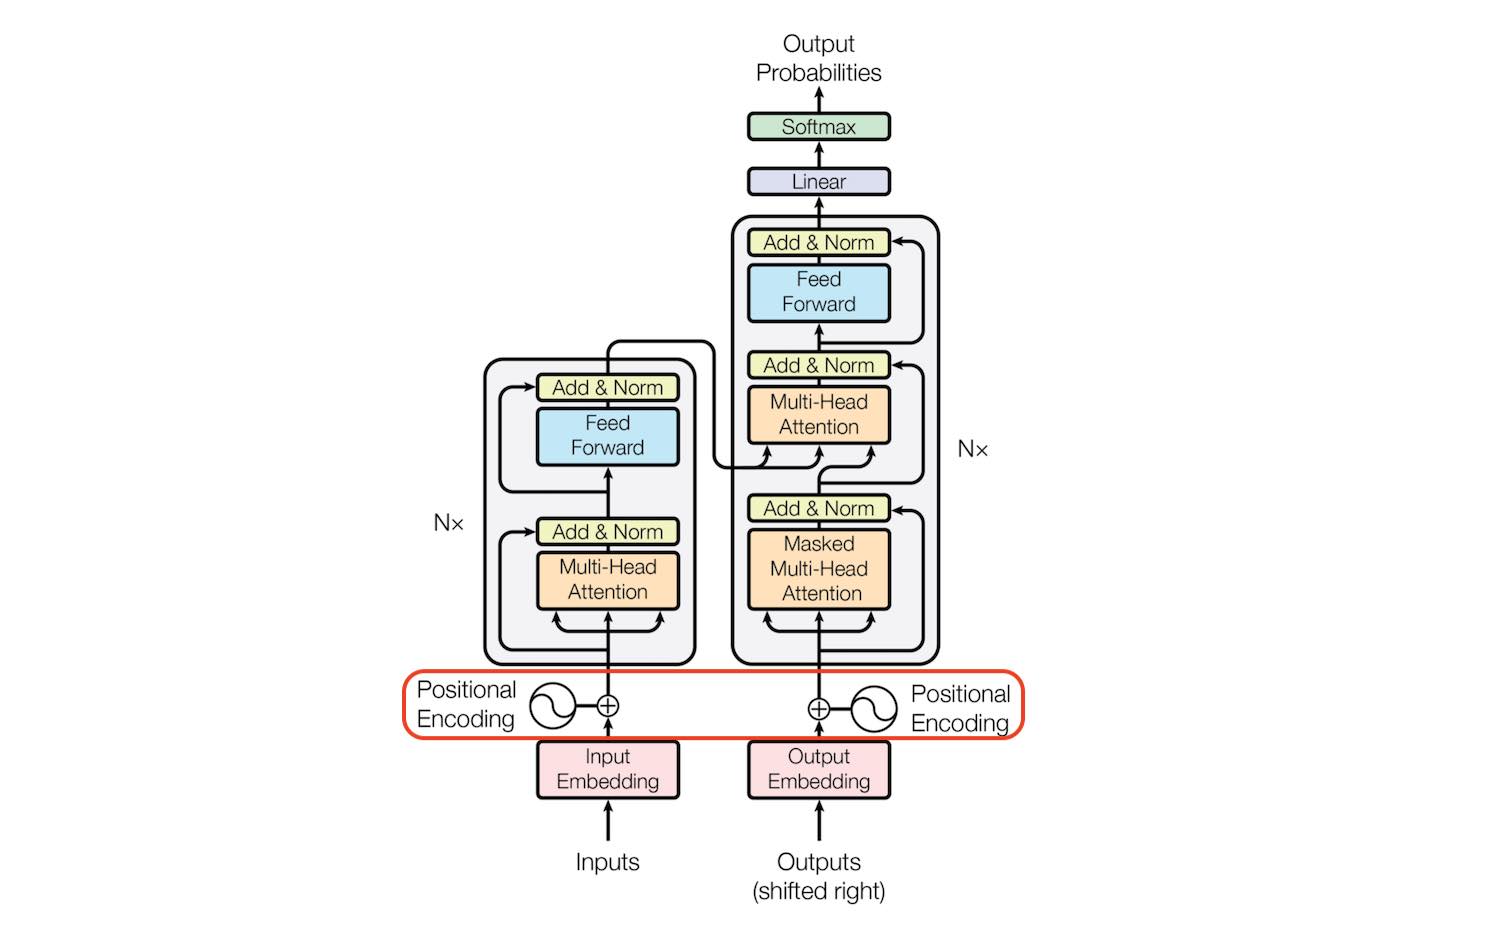
Where positional information is injected at the Transformer input stage. Source: Gowri Shankar
2. The Simplest Idea: Just Add the Position Index
The most naive approach is to attach position indices — 0, 1, 2, 3, … — directly to each token. But inserting a raw position number causes problems.
First, a position index is dimensionally incompatible with a token embedding vector. Embeddings are typically hundreds of dimensions wide; a position index is a single integer. Adding them directly is a category mismatch.
Second, large position indices create scale problems. Handling the 10th token and the 10,000th token consistently with the same scheme is non-trivial.
Third, a model needs relative position information as well as absolute position. Relationships like "three positions before the current token" are critical for language understanding.
For all these reasons, Transformers do not use raw position indices. Instead, they map each position index to a vector of the same dimensionality as the token embedding. Sinusoidal positional encoding performs this mapping using sine and cosine functions.
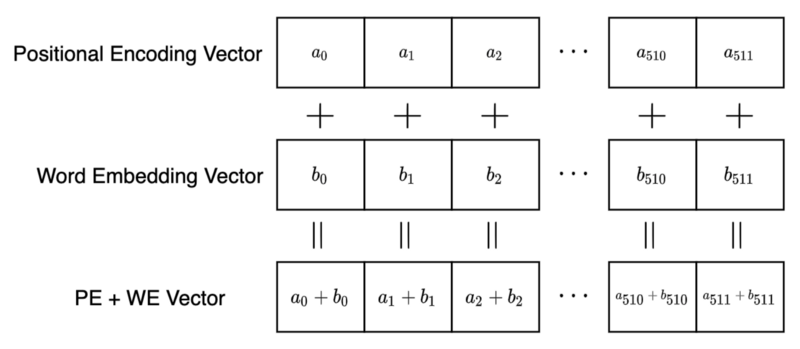
How the token embedding and positional encoding are summed to form the Transformer input. Source: Naoki Shibuya
3. The Formula Looks Long, but the Idea Is Simple
The sinusoidal positional encoding formula from the paper is:
PE(pos, 2i)     = sin(pos / 10000^(2i / d_model))
PE(pos, 2i + 1) = cos(pos / 10000^(2i / d_model))
Here, pos is the token's position — 0 for the first token, 1 for the second, and so on.
i is the dimension index within the vector. Even-indexed dimensions receive sine values; odd-indexed dimensions receive cosine values.
d_model is the embedding dimension size used by the Transformer. For d_model = 512, the positional encoding is also a 512-dimensional vector.
The formula looks complex, but the core idea is one thing: represent position pos simultaneously as oscillations at multiple frequencies. Lower dimensions use fast-oscillating waves; higher dimensions use slow-oscillating waves.
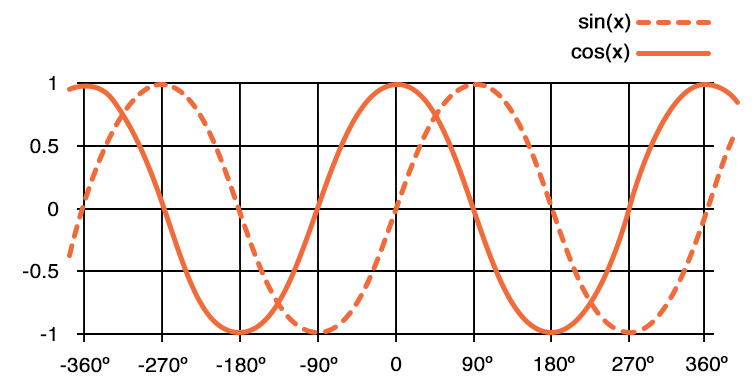
Sine waves are the basic building block for converting a position into a continuous signal value. Source: All About Circuits
4. Sine and Cosine Convert a Position into a Combination of Waves
Sine and cosine are periodic functions. At first glance, periodicity seems problematic — if the signal repeats, won't the model confuse different positions? The key is that sinusoidal positional encoding never uses a single sine value alone.
It uses sine and cosine at many different frequencies simultaneously. Some dimensions oscillate quickly over short periods; others vary slowly over long periods. Combining multiple wavelengths gives each position a pattern that is sufficiently distinct from every other position.
An analogy: instead of representing a position with a single color, represent it as a mixture ratio of many colors. A single red value leaves a lot of ambiguity, but specifying red, green, blue, brightness, and saturation together lets you distinguish far more states.
This structure also connects conceptually to Legendre approximation. Legendre approximation expresses a function as a combination of orthogonal polynomial basis functions. Sinusoidal positional encoding expresses a position as a combination of trigonometric basis components at multiple frequencies. Both approaches share the same high-level idea: represent a complex object as a superposition of basis components.
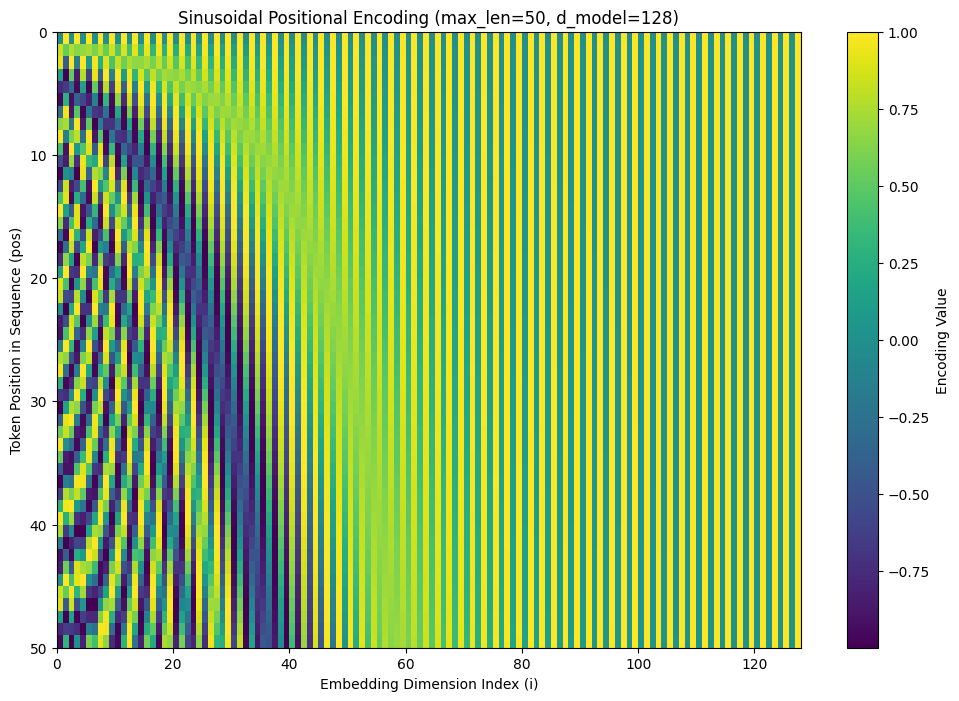
Positional encoding heatmap varying by position and dimension. Source: QuarkML
5. The Position Vector Is Added to the Token Embedding
The Transformer input is constructed by summing the token embedding and the positional encoding:
input_vector = token_embedding + positional_encoding
The token embedding captures "what this token is." The positional encoding captures "where this token is." By summing them, the model receives both meaning and position in a single vector.
For example, the token "cat" has the same token embedding whether it appears first or fifth in a sentence. But because the positional encodings differ, the final input vectors fed to the Transformer are different.
This approach is simple but effective. It injects positional information into the input without requiring any changes to the model architecture. Since self-attention computes token relationships from these vectors, positional information is indirectly reflected in the attention computation as well.
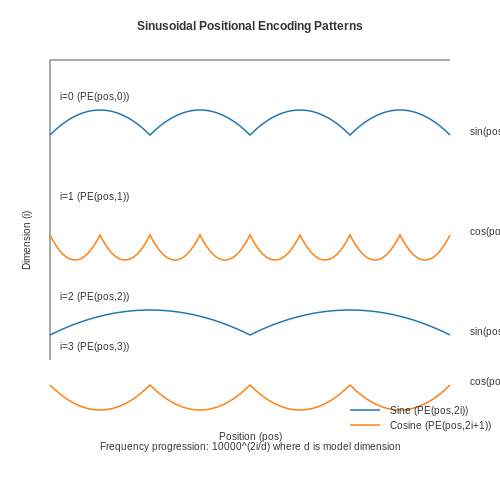
Illustration showing that the positional encoding takes the form of a matrix indexed by position and dimension. Source: Next Electronics
6. Why Use Both Sine and Cosine
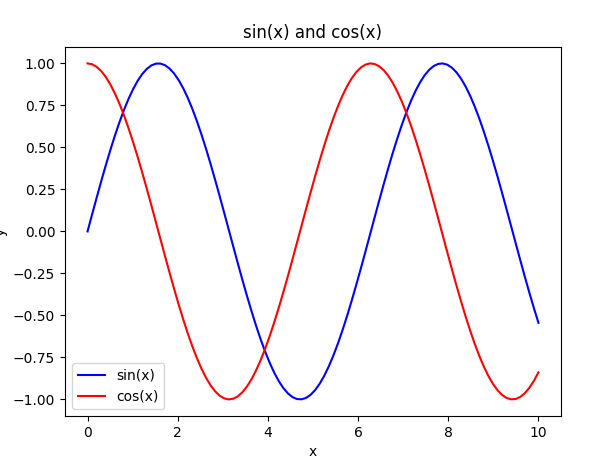
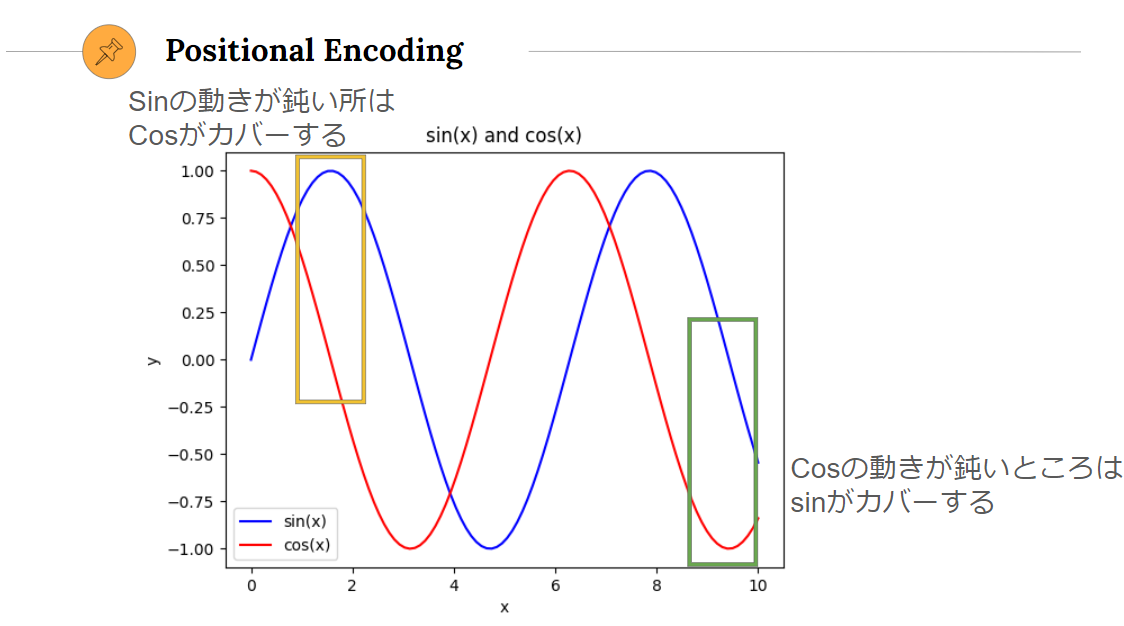
Sine alone produces values that vary by position. But pairing it with cosine provides two signals at the same frequency that are 90 degrees out of phase with each other.
This combination is advantageous for expressing positional offsets. The paper argues that the sinusoidal encoding makes it easy for the model to learn to attend by relative position, because for any fixed offset k, PE(pos + k) can be expressed as a linear function of PE(pos).
For beginners, a practical way to understand this: comparing the position vector of one token to that of another leaves the model with information about how far apart the two tokens are, in a form that is straightforward to compute.
Knowing only absolute position gives you "this token is at index 10." Being able to work with relative position gives you "this token is 3 positions after that one." The latter relationship is far more useful for language understanding.
A positional encoding perspective that accounts for both absolute and relative position. Source: nomulog
7. How This Differs from Learned Positional Embeddings
There are two broad approaches to injecting positional information:
- Generate position vectors from a fixed formula.
- Treat position vectors as trainable parameters and learn them from data.
Sinusoidal positional encoding takes the first approach. It does not change during training. Given a position index and a dimension index, the formula always returns the same value.
Learned positional embeddings take the second approach. The model directly adjusts each position's vector during training. This lets the model learn position representations that are well-suited to its data and task, but generalizing to sequence lengths not seen during training requires additional design consideration.
The advantage of the sinusoidal approach is that it is formula-based: no extra training parameters are introduced, and in principle the encoding can be computed for positions beyond those seen at training time. In practice, however, long-sequence generalization performance depends jointly on model architecture, training data, attention implementation, and context length configuration.
A comparison of different approaches to representing positional information. Source: nomulog
8. Parts of the Formula That Beginners Often Miss
First, positional encoding is not an algorithm that sorts or reorders tokens. It is an input representation scheme that attaches a positional signal to a sequence that is already ordered.
Second, sine and cosine are not decorative. They are the mechanism that projects a position into a high-dimensional vector by using waves at multiple frequencies.
Third, positional encoding alone does not enable sentence understanding. It is one ingredient. The actual semantic relationships are formed jointly by self-attention, feed-forward layers, normalization, and the learned weights.
Fourth, saying "Transformers don't know position" is really shorthand for "the architecture does not inherently process order." Once positional information is added to the input, self-attention operates on vectors that already carry that order signal.
9. What the Approximate Inference Perspective Reveals
Sinusoidal positional encoding takes positions — discrete integers — and maps them to combinations of continuous function values. Each position becomes not a single integer but a vector of wave components at multiple frequencies.
This connects to the broader idea of approximation. When a complex object is difficult to work with directly, it can be decomposed into a combination of tractable basis components. Just as Legendre approximation compresses a function into coefficients over a polynomial basis, sinusoidal positional encoding unfolds a position into a pattern over a trigonometric basis.
The Transformer does not interpret this positional pattern directly. Instead, it extracts the relevant relationships through learned attention weights and linear projections. In that sense, positional encoding is less "the result of understanding position" and more "the coordinate system that makes position understandable."
10. The One-Sentence Summary
Sinusoidal positional encoding converts each token's position into a high-dimensional vector of sine and cosine values at multiple frequencies, then adds that vector to the token embedding so the Transformer can distinguish token order.
The structure matters more than the formula itself. Transformers have no built-in notion of order, so position must be encoded as a vector and injected into the input. Sine and cosine provide the mechanism for representing each position as a combination of multiple wavelengths, giving the model an input representation from which it can readily learn both absolute position and relative distance.